LLM Consensus Matches or Outperforms the Best AI Models in Expert Evaluation Without Performance Degradation
 Galloway accuser could not foresee publishing-sector fallout, lawyer argues
 New York City Center revives In the Heights as a timely community story
 Vessel operator seeks witnesses after Vancouver grounding
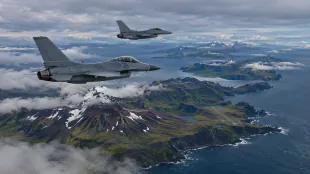 US Air Force deploys F-16 fighters to remote Aleutian base for readiness drill
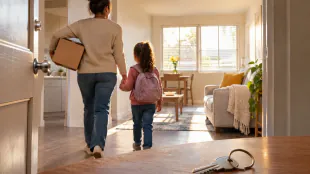 Bezos grant helps Seattle nonprofit move thousands of families toward housing
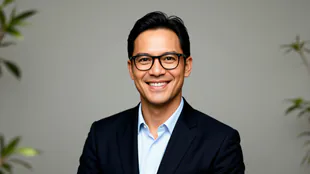
 Shrini Srivastava joins crew of Varanasi-Delhi Vande Bharat Sleeper service
 Nearly Half of Australian Workers Overqualified, Survey Finds
 RBI eases export-declaration compliance for individual service exporters
 India proposes more import entry points for drugs and medical devices
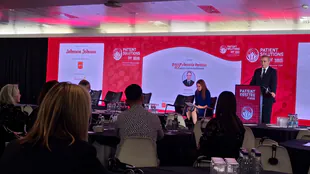 Derek Tierney Outlines Ten-Year Strategy for National Digital Health System
 NBC’s Steve Kornacki Reveals Tech Habits Ahead of Midterm Elections
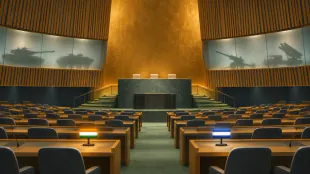 India and Israel oppose UN draft on regional conventional arms control
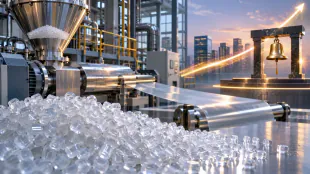 BLS Polymers shares open 65.3% above IPO price
 Capital-markets shares rally as Motilal Oswal and Angel One lead gains
 Latino Voters Defy ICE Fears, Turn Out in Record Numbers for Midterms
 ITC shares rise as analysts anticipate gradual cigarette-business recovery
 Reliance rally puts historical one-year return pattern in focus
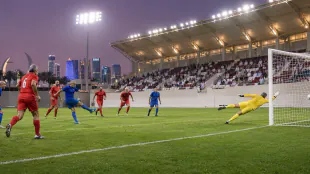 Kuwait edges Oman 1-0 in veterans Gulf Cup in Doha
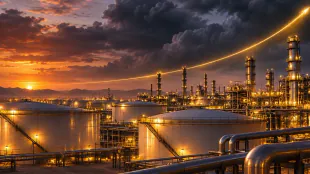 Saudi Aramco quarterly profit climbs 34.6% amid elevated oil prices
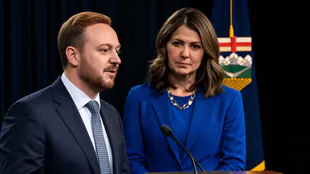
 Washington reports movement in Iran negotiations aimed at preventing escalation
 Korea’s Labor Share of GDP Hits Record Low Amid Semiconductor Boom
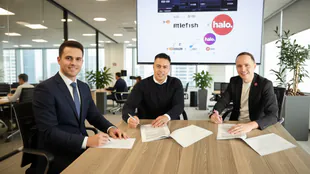 littlefish and Halo Dot Partner to Replace Payment Terminals with SoftPOS
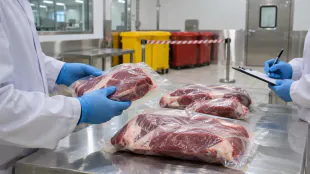 Kuwait inspectors destroy 115 kilograms of unverified meat in Farwaniya
 Egypt Accelerates Construction of 341km Sinai Railway Linking Arish and Taba
 John Schneider Admits Owes Millions in 'Dukes of Hazzard' Divorce Battle
A multi-model consensus system matches or outperforms GPT-5.4, Claude Opus 4.6 and Gemini 3.1 Pro across 100 expert-level questions infinance, law, medicine and technology, with no performance degradation.
SHERIDAN, WY / ACCESS Newswire / April 2, 2026 / LLM Consensus has released the results of its Expert-Domain Evaluation Benchmark v1.0, an independent study analyzing the performance of its multi-model consensus technology across 100 high-complexity questions in areas such as financial regulation, law, clinical medicine and technical architecture.
According to the results, the system matches or outperforms the best individual AI model across all evaluated questions, achieving measurable improvement in 44.9% of cases and with no instances of performance loss.
Key findings
In nearly half of the questions (45%), responses generated by the consensus system clearly outperformed those of the best individual model. The system was able to identify regulatory details that other models missed, resolve contradictions across sources, and deliver more complete answers.
In the remaining 55%, performance matched that of the best available model, ensuring a consistent baseline of quality without requiring users to choose between different models.
Additionally, in none of the 100 questions analyzed did the system produce a worse result than an individual model.
Performance by domain
The analysis focused on complex questions typical of regulated industries:
Clinical medicine (59% improvement): stronger performance in complex drug interactions, comorbidities, and application of clinical guidelines.
Financial regulation (50% improvement): advantages in scenarios combining multiple European regulatory frameworks such as DORA, PSD2, GDPR, and NIS2.
Legal analysis (44% improvement): greater precision in multi-jurisdictional and cross-regulatory compliance questions.
Technical architecture (30% improvement, 70% match): consistent results in system design decisions under regulatory and technical constraints.
Why it matters
The use of artificial intelligence in regulated industries continues to grow, yet no single model consistently excels across all domains. A system may perform well in financial regulation but fall short in clinical medicine, or vice versa.
LLM Consensus addresses this challenge by combining multiple leading models into a single response. It integrates technologies from OpenAI, Anthropic, Google, Mistral, and Meta, applying a synthesis process with cross-verification that leverages each model's strengths while reducing their weaknesses.
"Reliability is the core value proposition," the company said. "Users no longer have to decide which model to use. They get a single answer that consistently matches or outperforms the best available model for each case."
Evaluation methodology
The benchmark was specifically designed to assess tasks that require combining multiple sources of knowledge. Each question was evaluated by three independent reviewers from different AI providers, who scored responses blindly based on accuracy and quality.
Responses - from both the consensus system and individual models - were presented anonymously and in random order. Cases where sufficient agreement was not reached were classified as inconclusive and excluded from the final results.
The full dataset has been published to enable independent verification.
About LLM Consensus
LLM Consensus is an AI orchestration API that combines multiple advanced models into a single optimized response using patent-pending consensus technology.
The solution is available via REST API with different operating modes and is designed for developers and organizations in regulated sectors such as finance, healthcare, legal, and technology.
Press contact
Francisco Javier Nunez
Email: [email protected]
Web: llmconsensus.io
Patent pending: US 19/215,933 | EU EP25176020.3
This press release contains forward-looking statements based on current benchmark results. The evaluation was conducted using specific model versions as of March 2026; performance may vary with model updates. LLM Consensus is a system benchmark evaluating multi-model orchestration on expert synthesis tasks and should not be interpreted as a general-purpose comparison of individual AI models.
SOURCE: LLM Consensus
View the original press release on ACCESS Newswire
P.Costa--AMWN